Picture an online store with a small support team. Much of the inbox is some version of "where is my order", and every answer means opening the order system and copying a status into a reply. You've used ChatGPT, maybe called an AI API once, and now the team wants an agent to take that first pass.
This guide shows you how to build AI agents in Node.js by building that one, a piece at a time. By the end it looks orders up by itself, asks a person before it gives money back, and keeps answering when an AI service goes down. You start on your laptop with no API key and move to a hosted model when you're ready.
We ran every example on a deliberately tiny model and show you where it got things wrong. Those mistakes are much cheaper to meet here than in front of a customer.
What you need to build AI agents in Node.js
That order inbox makes a good first agent: the data lives in your system, the question is narrow, and a wrong answer is easy to catch. Refunds are different. They move money, so a person approves them.
An agent needs less than the word suggests. To build AI agents in Node.js you need three parts: tools the model can call, a loop that runs those tools and feeds the results back, and a model that is good at deciding when to call them. A tool is a function of yours, like an order lookup, that the model can ask to run. The model is a large language model (LLM), the kind behind ChatGPT. Memory stores, graphs and dashboards are optional, and most first agents skip them.
Here's the plan. This guide builds one support agent end to end with the intellinode npm package, in small files: a plain JavaScript tool that answers order questions, a loop, a provider switch, an MCP server and client that serve the same tool, a refund approval step that waits for a person, and a production wrapper that falls back to another provider when one is down. This follows Anthropic's advice in Building effective agents: start with direct LLM calls and add layers only when the simple version falls short.
Two terms from that list will keep coming up. A provider is whoever runs the model for you, and MCP (the Model Context Protocol) is an open standard for sharing tools between AI apps. You develop on a local Ollama model with no API key (Ollama runs open models on your own machine), then move to OpenAI, Claude or Gemini by changing one line.
By the end of the guide, the pieces fit together like this:
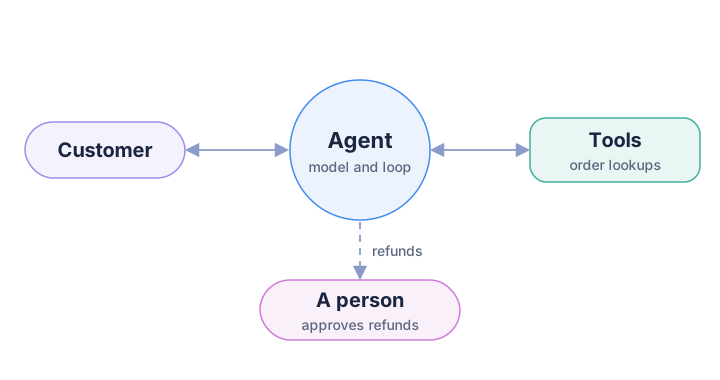
The finished agent. It answers the customer, looks orders up with its tools, and sends refunds to a person first.
Install IntelliNode and pick a model
The files that follow all need two things: the library and a model to talk to.
You need Node.js 18 or newer. The package has three runtime dependencies and its own TypeScript types (see the installation page).
npm i intellinode

# local models for development, no key needed
ollama pull qwen2.5:0.5b   # about 400 MB, fine for wiring things up
ollama pull qwen3:8b       # 5.2 GB, a better fit for real tool use
Every snippet was run on Node.js 20 against Ollama with qwen2.5:0.5b. The 0.5B in its name means about half a billion parameters, a rough measure of size. A model that small runs on any laptop, which is why we tested with it. It is also poor at deciding when to call a tool, so you meet the failure modes early. For anything a customer reads, use a larger local model such as qwen3, which Ollama lists with tool support, or a cloud model.
Cloud keys go in environment variables on your server: OPENAI_API_KEY, ANTHROPIC_API_KEY and GEMINI_API_KEY. Never put them in a browser bundle, where anyone can read them.
Define the tools the model can call
With a model running, start on the first of the three parts: the order lookup your team does by hand today.
In code, a tool is a name, a description, a JSON Schema for its arguments and a handler. JSON Schema is a standard way to describe JSON data, here the arguments and their types, and the handler is the function that does the work. The model never sees the handler. The name, description and schema alone decide whether it calls the tool and with what arguments.
// order-tools.js: plain functions the agent can call
const ORDERS = {
  'A-1001': { status: 'shipped', carrier: 'DHL', eta: '2026-10-02' },
  'A-1002': { status: 'processing', carrier: null, eta: '2026-10-06' },
};

const tools = [
  {
    name: 'get_order_status',
    description:
      'Look up the shipping status, carrier and expected delivery date of a customer order. ' +
      'Call it whenever the customer gives an order id such as A-1001.',
    parameters: {
      type: 'object',
      properties: {
        orderId: { type: 'string', description: 'The order id, for example A-1001' },
      },
      required: ['orderId'],
    },
    handler: async ({ orderId }) => {
      const order = ORDERS[orderId];
      if (!order) throw new Error(`No order found with id ${orderId}`);
      return { orderId, ...order };
    },
  },
];

module.exports = { tools };
The description says when to call the tool, not only what it does, and the orderId property shows the id format. The handler throws on an unknown id instead of returning null, because a thrown error reaches the model as text, so it can tell the customer instead of guessing.
Wording matters more than you would expect. With qwen2.5:0.5b, "What is the status of order A-1001?" triggered the tool in 16 of 19 runs. "Where is my order A-1001?" triggered it in 1 of 15 runs across the prompts we tried, and most other runs asked the customer for the id they had just typed. Test the phrasings your customers actually use on the model you plan to ship.
Run the LLM tool calling loop with runTools
The model can't run your tool itself. It can only reply with a request, in effect "call get_order_status with A-1001", and the second part, the loop, does the running.
By hand, the loop is: send the messages and tool definitions, run the tools the reply asks for, append calls and results in the provider's format, and repeat until the model answers with text. Every provider formats tool calls differently, and the loop needs a step cap. IntelliNode's runTools handles both. Below, Chatbot talks to the local Ollama model and OpenAICompatibleInput holds the conversation: the system prompt (the agent's standing instructions) and the customer's message.
// agent.js
const { Chatbot, OpenAICompatibleInput } = require('intellinode');
const { tools } = require('./order-tools');

const SYSTEM =
  'You are a support agent for an online store. ' +
  'Always call get_order_status before you answer a question about an order. Keep answers short.';

async function main() {
  const bot = new Chatbot(null, 'ollama', null, { model: process.env.OLLAMA_MODEL || 'qwen2.5:0.5b' });

  const input = new OpenAICompatibleInput(SYSTEM);
  input.addUserMessage('What is the status of order A-1001?');

  const { text, steps, toolCalls } = await bot.runTools(input, tools, {
    maxSteps: 4,
    onToolCall: (name, args) => console.log('calling', name, args),
    onToolResult: (name, result, isError) => console.log('result', name, isError ? 'error' : 'ok'),
  });

  console.log(text);
  console.log(toolCalls, steps.map((step) => step.name));
}

main();

// calling get_order_status { orderId: 'A-1001' }
// result get_order_status ok
// The order A-1001 has been shipped. The carrier is DHL and the expected delivery date is 2026-10-02.
// 1 [ 'get_order_status' ]
What to know about the result:
textis the answer,stepslists each executed tool with its arguments, result andisError, andtoolCallsis the count.maxStepscounts tool rounds (default 5), and the model gets one more call after the last round. SomaxSteps: 4means at most five model calls per question, which is your cost ceiling per request. If the model still wants tools,runToolsthrows "runTools stopped after 4 tool rounds without a final answer".- A throwing handler does not crash the loop. Asked about order A-9999, the step came back as
Error: No order found with id A-9999withisError: true, and the model told the customer it could not find it. onToolCallandonToolResultare where logging and audit records go.
One caveat: runTools appends the tool calls and results to the input you pass in. Create a fresh input per customer request, or one customer's order data leaks into the next conversation.
TypeScript
In TypeScript, the same agent uses the package's own types. Top-level await needs an ES module, so use an .mts file or set "type": "module" in package.json.
// agent.mts
import { Chatbot, OpenAICompatibleInput, type RunToolsResult } from 'intellinode';

const bot = new Chatbot(null, 'ollama', null, { model: process.env.OLLAMA_MODEL || 'qwen2.5:0.5b' });
const input = new OpenAICompatibleInput(
  'You are a support agent for an online store. Always call get_order_status before you answer a question about an order.',
);
input.addUserMessage('What is the status of order A-1001?');

const result: RunToolsResult = await bot.runTools(input, [{
  name: 'get_order_status',
  description: 'Look up the shipping status of an order by id',
  parameters: { type: 'object', properties: { orderId: { type: 'string' } }, required: ['orderId'] },
  handler: async ({ orderId }: { orderId: string }) => ({ orderId, status: 'shipped', eta: '2026-10-02' }),
}], { maxSteps: 4 });

console.log(result.text, result.toolCalls);
Switch from Ollama to OpenAI, Claude or Gemini
The agent works on your laptop. For customers you'll want a stronger hosted model, and this is where the one line change comes in.
That one line matters for a business reason: lock-in. Most Node.js tutorials on OpenAI function calling (OpenAI's name for tool calling) are written against one vendor's SDK (its own client library), so moving means rewriting the loop. Here the loop, tools and tests stay put, and you can price one workload on three vendors in an afternoon.
The agent above is tied to Ollama by one line and one input class. Put both behind a small factory and the provider becomes a config value:
// switch.js
const { Chatbot } = require('intellinode');
const { tools } = require('./order-tools');

const SYSTEM =
  'You are a support agent for an online store. ' +
  'Always call get_order_status before you answer a question about an order. Keep answers short.';

const bots = {
  ollama: () => new Chatbot(null, 'ollama', null, { model: process.env.OLLAMA_MODEL || 'qwen2.5:0.5b' }),
  openai: () => new Chatbot(process.env.OPENAI_API_KEY, 'openai'),
  anthropic: () => new Chatbot(process.env.ANTHROPIC_API_KEY, 'anthropic'),
  gemini: () => new Chatbot(process.env.GEMINI_API_KEY, 'gemini'),
};

async function answer(question) {
  const bot = bots[process.env.LLM_PROVIDER || 'ollama']();
  const input = Chatbot.createInput(bot.provider, SYSTEM);   // ChatGPTInput, AnthropicInput, GeminiInput...
  input.addUserMessage(question);
  const { text } = await bot.runTools(input, tools, { maxSteps: 4 });
  return text;
}

answer('What is the status of order A-1002?').then(console.log);
Chatbot.createInput picks the matching input class. The same tool definition is converted for each API, and so are the calls and results: function call items for the OpenAI Responses API, tool_use blocks for Claude and functionCall parts for Gemini. LLM_PROVIDER=anthropic node switch.js is the whole migration.
The current defaults are gpt-5.5, claude-sonnet-5 and gemini-3.6-flash. Pin a model in production with model in the third argument of createInput, so a library upgrade never changes your bill. On Claude, maxTokens defaults to 2048 and thinking (Claude's reasoning before it answers) counts toward it, so raise it if answers get cut.
The same code reaches Groq, OpenRouter or LM Studio through the OpenAI-compatible providers. One exception: Cohere's input never sends tools, so runTools on Cohere returns plain text with zero steps and no error.
Use MCP servers as agent tools in Node.js
Changing the model took one line. Moving the tools out of your repo takes a little more.
Plain functions work while the agent and tools share a repo. Once another team owns the order service, or Claude Code and Cursor (two AI coding assistants) should use the same tools, put them behind an MCP server. An MCP server offers tools over the protocol, so any MCP client can list and call them. IntelliNode's MCPServer takes almost the same shape, with inputSchema in place of parameters:
// order-server.js: the same tools, served over MCP
const { MCPServer } = require('intellinode');
const { tools } = require('./order-tools');

const server = new MCPServer({
  name: 'order-tools',
  version: '1.0.0',
  instructions: 'Tools for looking up customer orders.',
  tools: tools.map(({ name, description, parameters, handler }) => ({
    name,
    description,
    inputSchema: parameters,
    handler,
  })),
});

server.startStdio();   // stdout carries the protocol, so log to stderr
The agent passes an MCPClient where the tools array used to be:
// mcp-agent.js
const path = require('path');
const { Chatbot, OpenAICompatibleInput, MCPClient } = require('intellinode');

const SYSTEM =
  'You are a support agent for an online store. ' +
  'Always call get_order_status before you answer a question about an order. Keep answers short.';

async function main() {
  const orders = new MCPClient({ command: 'node', args: [path.join(__dirname, 'order-server.js')] });

  try {
    const bot = new Chatbot(null, 'ollama', null, { model: process.env.OLLAMA_MODEL || 'qwen2.5:0.5b' });
    const input = new OpenAICompatibleInput(SYSTEM);
    input.addUserMessage('What is the status of order A-1001?');

    // runTools lists the server's tools on first use, no connect() needed
    const { text, steps } = await bot.runTools(input, orders, { maxSteps: 4 });
    console.log(text);
    console.log(steps.map((step) => step.name));
  } finally {
    await orders.close();   // stops the server subprocess
  }
}

main();
Before you rely on it:
- The client runs
order-server.jsas a stdio subprocess, a child process it talks to over standard input and output. For a remote server, usenew MCPClient({ url, headers })over Streamable HTTP, MCP's web transport. It handles both the 2026-07-28 protocol and the older initialize handshake. - Always call
close(). A test script that skipped it was still running six seconds after its last line, held open by the subprocess. - Community servers plug in the same way:
command: 'npx', args: ['-y', '@modelcontextprotocol/server-filesystem', './kb']gives the agent file tools limited to one folder. runToolstakes one tool source per call, so an agent that needs both kinds should get all its tools from one MCP server.MCPServerserves tools only, checks only top-levelrequired,typeandenum, and has no authentication. Over HTTP it binds to 127.0.0.1 by default; add your own auth before you expose it.
Over MCP the small model used the tool in 12 of 18 runs, and in one miss it invented a "pending confirmation" status that exists nowhere in the data, a case the production section handles.
The official Build an MCP client tutorial writes this loop by hand against the Anthropic SDK, a good way to learn the protocol. The MCP client and MCP server pages list every option, plus npx -y intellinode mcp, a ready server of cross-provider tools for Claude Code and Cursor.
Keep a human in the loop for risky actions
So far the agent only reads data, so the worst case is a wrong answer someone catches. Refunds are the other kind of action.
runTools runs every tool it is given as soon as the model asks. That is right for reads and wrong for refunds. For actions that move money, keep the tool out of the loop: put the definition on the input, read tool_calls from chat(), which makes a single model call and runs nothing, and continue only after someone approves.
// refund.js: the model proposes, a person approves
const readline = require('readline/promises');
const { Chatbot, OpenAICompatibleInput } = require('intellinode');

const issueRefund = {
  type: 'function',
  function: {
    name: 'issue_refund',
    description: 'Refund a customer order. Use it only when the customer asks for a refund.',
    parameters: {
      type: 'object',
      properties: {
        orderId: { type: 'string' },
        amount: { type: 'number', description: 'Amount in USD' },
      },
      required: ['orderId', 'amount'],
    },
  },
};

async function main() {
  const bot = new Chatbot(null, 'ollama', null, { model: process.env.OLLAMA_MODEL || 'qwen2.5:0.5b' });
  const input = new OpenAICompatibleInput(
    'You are a support agent for an online store. Always call issue_refund when a customer asks for a refund.',
    {
      tools: [issueRefund],
      toolChoice: 'auto',   // 'auto' | 'none' | 'required'
    },
  );
  input.addUserMessage('Order A-1002 arrived broken. Please refund the 49.90 USD I paid.');

  const [reply] = await bot.chat(input);
  if (!reply || !reply.tool_calls) return console.log(reply);

  const rl = readline.createInterface({ input: process.stdin, output: process.stdout });
  const results = [];
  for (const call of reply.tool_calls) {
    const args = JSON.parse(call.function.arguments);   // arguments arrive as a JSON string
    const ok = call.function.name === 'issue_refund'   // small models sometimes invent tool names
      ? await rl.question(`Approve ${call.function.name} ${JSON.stringify(args)}? (y/n) `)
      : 'n';
    const content = ok.trim() === 'y'
      ? { refunded: true, orderId: args.orderId, amount: args.amount }   // call your payments API here
      : { refunded: false, reason: 'A support lead declined the refund.' };
    results.push({ id: call.id, name: call.function.name, content });
  }
  rl.close();

  input.addToolCalls(reply.tool_calls, reply.content);
  input.addToolResults(results);
  const [answer] = await bot.chat(input);
  console.log(answer);
}

main();
In about half our runs the model proposed issue_refund, most often as {"amount":49.9,"orderId":"A-1002"}; in the rest it skipped the tool, usually asking for the order number again. addToolCalls records that request, addToolResults records the outcome, and the second chat() writes the reply. A declined refund is a normal result: with "n", the model apologized and pointed the customer to the support team.
The small model also invented things. After an approval it added that the refund was "sent to your billing address", which no tool returned. Some proposals asked for 51 or -49.9 USD instead of 49.90, and once it called a made-up getOrderId tool. That is why the approver sees the exact arguments and only issue_refund reaches the prompt. Those mistakes argue for a larger model, and for letting the approver see the final message while you build trust.
In a real service the approval is a queue in your admin tool, not a terminal prompt. Store the pending call id, name and arguments with the ticket, and rebuild the input with addToolCalls when the decision arrives.
Production checklist for a Node.js AI agent
Every piece now works on its own. What's left is making the agent behave when providers are slow or down and when customers leave before the answer arrives.
Here is the agent from switch.js with request limits and fallback lanes added. Each lane is one provider, tried in order when the one before it hits a provider-side problem:
// support-agent.js
const { Chatbot } = require('intellinode');
const { tools } = require('./order-tools');

const SYSTEM =
  'You are a support agent for an online store. ' +
  'Always call get_order_status before you answer a question about an order. Keep answers short.';

const REQUEST = { timeout: 30000, retries: 2, retryDelay: 500 };

const lanes = {
  primary: (signal) => new Chatbot(process.env.OPENAI_API_KEY, 'openai', null, { ...REQUEST, signal }),
  backup: (signal) => new Chatbot(process.env.ANTHROPIC_API_KEY, 'anthropic', null, { ...REQUEST, signal }),
  local: (signal) => new Chatbot(null, 'ollama', null, {
    ...REQUEST, timeout: 120000, signal, model: process.env.OLLAMA_MODEL || 'qwen2.5:0.5b',
  }),
};

// provider-side problems: move to the next lane
const isProviderProblem = (error) =>
  ['ETIMEDOUT', 'ECONNREFUSED', 'ENOTFOUND'].includes(error.code) ||
  error.status === 429 || error.status >= 500;

async function answer(question, { signal, order = ['primary', 'backup', 'local'] } = {}) {
  let lastError;
  for (const lane of order) {
    const bot = lanes[lane](signal);
    const input = Chatbot.createInput(bot.provider, SYSTEM);   // a fresh input for every attempt
    input.addUserMessage(question);
    try {
      const result = await bot.runTools(input, tools, { maxSteps: 4 });
      return { lane, ...result };
    } catch (error) {
      // AbortError, a 401 bad key or the maxSteps error should surface, not fall through
      if (!isProviderProblem(error)) throw error;
      console.warn(`lane ${lane} failed: ${error.code || error.status}`);
      lastError = error;
    }
  }
  throw lastError;
}

module.exports = { answer };
And a small endpoint, so the keys stay on the server:
// server.js: the agent behind your own endpoint, keys stay on the server
const http = require('http');
const { answer } = require('./support-agent');

http.createServer(async (req, res) => {
  const controller = new AbortController();
  res.on('close', () => { if (!res.writableEnded) controller.abort(); });   // the customer left

  try {
    const chunks = [];
    for await (const chunk of req) chunks.push(chunk);
    const { question = '' } = JSON.parse(Buffer.concat(chunks).toString() || '{}');   // in the try, so bad JSON cannot crash the server
    const { lane, text, toolCalls } = await answer(question, { signal: controller.signal });
    const needsOrderData = /\b[A-Z]-\d{4}\b/.test(question);
    const escalate = needsOrderData && toolCalls === 0;   // answered without looking anything up
    res.end(JSON.stringify({ lane, escalate, text: escalate ? null : text }));
  } catch (error) {
    if (error.name !== 'AbortError') console.error(error);
    if (!res.writableEnded) res.writeHead(502).end(JSON.stringify({ escalate: true }));
  }
}).listen(3000);
With the first two lanes pointed at dead endpoints, the log showed lane primary failed: ECONNREFUSED, then lane backup failed: ENOTFOUND, and the local lane answered. The checklist behind these files:
- Cap the steps. The maxSteps error has no status or code, so the fallback rethrows it. Treat it as a bug in your prompt or tools.
- Do the timeout math.
timeoutapplies per attempt and per model call, and retries cover 429, the common 5xx codes and network errors. Five calls times three attempts times 30 seconds is over seven minutes in the worst case, far too long for live chat, so tune the request options per channel. - Cancel abandoned work. The
res.on('close')line aborts the call through an AbortController when the customer leaves, so you stop paying for answers nobody reads. - Catch unreachable hosts. Network failures have no HTTP status, so a check on
statusalone never falls back when a host is down. HenceECONNREFUSEDandENOTFOUND. A 401 is your bug, so it surfaces. - Use a fresh input per attempt. A half-finished tool conversation from OpenAI is not valid input for Claude.
- Distrust answers that skipped the tools. The
toolCalls === 0check sends those to a person. - Check authorization in the handler. A customer can type anyone's order id. Look the order up with the customer id from your session. A system prompt is not access control.
- Keep the automatic loop read-only. Fallback reruns the loop on the next lane, so a tool can run twice.
The model routing page extends the lanes idea to quality, cost and private data.
When a bigger agent framework fits better
The whole agent fits in a handful of short files. It helps to know where that approach stops and a larger framework earns its weight.
For agents, IntelliNode is deliberately small: a Chatbot class with one tool loop, an MCP client and server, and a ready coding agent. It has no memory store, tracing UI, React hooks or durable execution (runs that survive a crash and resume where they stopped), and when you need those, other tools fit better. From their official docs, checked on September 30, 2026:
- OpenAI Agents SDK (
@openai/agents): handoffs, guardrails, sessions, tracing and MCP tools, with other models through an AI SDK extension. Good for multi-agent handoffs with tracing built in. - Vercel AI SDK: a
ToolLoopAgentwithstopWhenloop control, an MCP client (createMCPClientin@ai-sdk/mcp) and UI hooks such asuseChatfor React, Vue, Svelte and Angular. Pick it when the agent streams into a web UI. - Mastra: a TypeScript framework with agents, workflows that can suspend and resume, memory backed by a storage provider, and an interactive Studio UI. Pick it when you want those pieces included.
- LangGraph.js: low-level orchestration for long-running, stateful agents, with durable execution, checkpointing and human-in-the-loop support. Pick it when an agent must resume after a crash or a day-long wait.
Choose IntelliNode for a backend agent that swaps providers by config, runs locally on Ollama, and stays small enough for a new teammate to read in an hour. For a wider comparison, see How to Choose a Node.js LLM Library in 2026.
FAQ
A few questions come up with almost every first agent.
What is the best model for an AI agent in Node.js?
Use the model that picks the right tool for your own questions, not the best benchmark score. Run 20 or so real customer questions through a cloud model such as gpt-5.5 or claude-sonnet-5 and a local model of about 8B parameters. A 0.5B model is fine for wiring code, but even with our best prompt it skipped the tool in 3 of 19 direct runs and 6 of 18 over MCP.
Can a Node.js AI agent run fully offline with Ollama?
Yes. new Chatbot(null, 'ollama', null, { model }) needs no key, and the same runTools and MCPClient code runs with no internet connection. The limit is model quality on your hardware, not the code.
How many tool steps should an AI agent be allowed?
Allow the tool rounds a correct answer needs, plus a little room. A lookup agent like this needs one or two, so maxSteps: 4 leaves slack without letting a confused model loop. If you hit the maxSteps error often, fix the tool descriptions before raising the limit.
Can I build the agent in TypeScript?
Yes. The package ships index.d.ts, so Chatbot, the input classes and RunToolsResult are typed with no @types package. The code is CommonJS, and ESM named imports work, as agent.mts shows. Import RunToolsResult with the type modifier: it exists only as a type, so a plain import fails under verbatimModuleSyntax and under Node's type stripping.
Can Claude Code or Cursor use the same tools?
Yes. order-server.js is a standard stdio MCP server, so you can register it with claude mcp add order-tools -- node /path/to/order-server.js or add it to .cursor/mcp.json. Your agent and your coding assistant then share one implementation of the tools.
Next step
The quickest way to make this stick is to run the smallest file yourself. Install the package, pull a local model, and run agent.js from this guide:
npm i intellinode
ollama pull qwen2.5:0.5b
node agent.js
Then read the tool calling guide for the other tool formats and the manual tool call API. For a cloud model, run switch.js with LLM_PROVIDER and your key set.