Picture the support inbox at an online retailer on a Monday morning. Ticket after ticket asks the same thing: where is my order? Each one means a rep checks the order, then the carrier, then types a reply.
A plain chatbot can't help. It doesn't know your orders, so it guesses. An AI agent can look things up on its own and hand anything risky to a person. This guide shows how to build an AI agent in Python for that job, without a big framework.
You'll start with the idea, write the agent in one file, run it on a hosted model and on a free one on your laptop, then add the checks you'd want before customers see it. Along the way, a tiny local model shows where things quietly go wrong.
What an AI agent is made of
Strip away the hype and an agent is a small pattern: give a model a short list of functions, run a loop that executes the calls it asks for, send the results back, and stop after a fixed number of steps. That loop is the agent. Everything else is guardrails.
That gives an agent four parts: a model, a set of tools, a loop and a stop rule. A tool is just a function of yours the model may request. The model decides which tool to call. Your code runs the tool. The loop repeats until the model answers in plain text or hits the step limit.
Anthropic's Building effective agents describes agents the same way: models using tools in a loop, with stopping conditions such as a maximum number of iterations. It also recommends starting with large language model (LLM) APIs directly before adopting a framework, which is the path taken here.
Back to that support inbox. Each "where is my order" ticket takes a rep two lookups, the order system and then the carrier. An agent with tools does both lookups itself and hands anything involving money to a human. Those two lookups become its first two tools.
How to build an AI agent in Python in four steps
Wired together, those parts form a cycle. Every agent loop, in any framework, repeats the same four steps:
- Ask. Send the conversation and the tool list to the model.
- Check. If the reply is text, you are done. If it is a tool call, keep going.
- Run. Execute each requested function with the arguments the model chose.
- Send back. Add the results to the conversation and go back to step 1.
The OpenAI function calling guide documents the same cycle, with two details that shape your code: arguments arrive as a JSON string, and a model may call several functions in one turn.
The stop rule is the part most tutorials skip. Every pass is a full model call that resends the whole conversation. At 1,000 tickets a day and three calls per ticket you pay for 3,000 calls a day, and one confused conversation without a cap can burn twenty on its own. A max_steps cap keeps the bill bounded.
Here is the whole cycle in one picture:
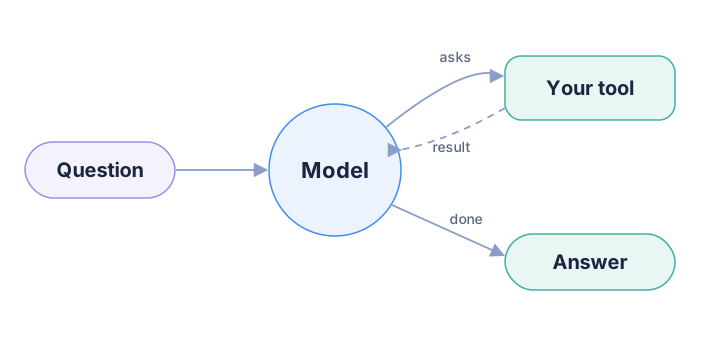
The model asks your tool for data, gets the result back, and answers once it has enough.
None of the four steps cares who made the model, so the same code will run on OpenAI, Claude or a local Ollama model (which runs open models on your own machine) by changing one constructor and the model name.
Step 1: Install Intelli and define your tools
Now for code. You'll build the order status agent in under 100 lines of plain Python on top of the Chatbot class from Intelli, a library that puts several model providers behind one interface. You need Python 3.10 or newer.
pip install intelli
Keep your data access in normal Python functions and describe each one with a JSON schema, a short description of the function and its arguments. The model reads the descriptions to decide what to call, so write them for a new colleague, not for a linter. Part 1 of order_agent.py holds stand-in data, both lookups, their descriptions and a small converter.
# order_agent.py (part 1)
import json

from intelli.model.input.chatbot_input import ChatModelInput
from intelli.utils.model_helper import is_reasoning_model

# Stand-ins for your order database and your carrier's API
ORDERS = {
    "A-1001": {"status": "shipped", "carrier": "DHL", "tracking_number": "DHL-778120"},
    "A-1002": {"status": "processing", "carrier": None, "tracking_number": None},
}
SHIPMENTS = {"DHL-778120": {"eta": "2026-10-03", "last_scan": "Leipzig hub"}}


def get_order_status(order_id):
    order = ORDERS.get(order_id.strip().upper())
    return order or {"error": f"order {order_id} not found"}


def get_shipment_eta(tracking_number):
    return SHIPMENTS.get(tracking_number.strip(), {"error": "unknown tracking number"})


TOOL_SPECS = [
    {
        "name": "get_order_status",
        "description": "Look up an order by id. Returns status, carrier and tracking number.",
        "parameters": {
            "type": "object",
            "properties": {"order_id": {"type": "string", "description": "Order id such as A-1001"}},
            "required": ["order_id"],
        },
    },
    {
        "name": "get_shipment_eta",
        "description": "Get the delivery estimate for a carrier tracking number.",
        "parameters": {
            "type": "object",
            "properties": {"tracking_number": {"type": "string"}},
            "required": ["tracking_number"],
        },
    },
]
TOOLS = {"get_order_status": get_order_status, "get_shipment_eta": get_shipment_eta}


def tools_for(provider, model):
    """Wrap the same specs in the format each API expects."""
    if provider == "anthropic":
        return [{"name": t["name"], "description": t["description"],
                 "input_schema": t["parameters"]} for t in TOOL_SPECS]
    if is_reasoning_model(model):  # GPT-5 family runs on the Responses API
        return [{"type": "function", **t} for t in TOOL_SPECS]
    return [{"type": "function", "function": t} for t in TOOL_SPECS]
The converter, tools_for, exists because Intelli passes your tool list to the provider as given, and the APIs expect different shapes: OpenAI's chat completions API nests the schema under function, GPT-5 models on its newer Responses API use a flat format, and Anthropic wants input_schema. The tool calling docs show each one.
It keeps one TOOL_SPECS list and converts at the edge, so adding a tool is one new entry. It uses is_reasoning_model, the same check Intelli uses to route a model to the Responses API.
Step 2: Write the agent loop
The four steps now become one function. This is the whole agent, and it stays the same no matter which provider you use.
# order_agent.py (part 2)
SYSTEM = ("You are an order support assistant. Use the tools to answer. "
          "Never guess an order status or a delivery date.")


def run_tool(name, raw_args):
    fn = TOOLS.get(name)
    if fn is None:
        return {"error": f"unknown tool {name}"}
    try:
        return fn(**json.loads(raw_args or "{}"))
    except (json.JSONDecodeError, TypeError) as err:
        return {"error": f"bad arguments for {name}: {err}"}


def run_agent(bot, model, question, max_steps=5):
    chat = ChatModelInput(SYSTEM, model=model, tools=tools_for(bot.provider, model),
                          temperature=0, max_tokens=1000)
    chat.add_user_message(question)

    for step in range(max_steps):
        if step == max_steps - 1:
            chat.tools = None  # last step: no tools, so the model must answer in text
        reply = bot.chat(chat)[0]

        if not (isinstance(reply, dict) and reply.get("type") == "tool_response"):
            return reply  # plain text means the agent is done

        results = []
        for call in reply["tool_calls"]:  # a model can ask for several tools at once
            name, args = call["function"]["name"], call["function"]["arguments"]
            output = run_tool(name, args)
            print(f"step {step + 1}: {name}({args}) -> {output}")
            results.append({"tool": name, "arguments": args, "result": output})

        chat.add_assistant_message("Calling tools: " + ", ".join(r["tool"] for r in results))
        chat.add_user_message("Tool results: " + json.dumps(results) +
                              "\nCall another tool if you still need data. Otherwise answer the question.")
    return "Sorry, I could not finish this request."
Why the loop looks like this:
bot.chat(chat)always returns a list. When the model wants a tool, the first item is a dict with"type": "tool_response"and atool_callslist, each call carryingfunction.nameandfunction.argumentsas a JSON string. The shape is the same for OpenAI chat completions, the GPT-5 Responses API and Anthropic, so the loop has no provider branches.- The inner loop over
tool_callsmatters. Claude can ask for several lookups in one turn, such as two order ids in one question, and Intelli collects everytool_useblock (Anthropic's term for a tool request) into that list. Read only the first call and you silently drop work. - Results go back as a user message, because
ChatModelInputhas no tool role message with atool_call_id, the field some APIs use to tie a result to its call. You lose native tool result threading. In exchange the history is plain text on every provider, and removing tools on the last step cannot orphan a tool call. - On the final step,
chat.tools = Noneforces a text answer, so the customer always gets a reply. run_toolreturns errors as data. A wrong order id becomes a message the model can react to instead of an exception that kills the request.
Temperature sets how much the output varies, and 0 makes it as repeatable as possible. temperature=0 is safe across providers. Intelli leaves it out for GPT-5 models and for the Claude 5 family, which reject sampling parameters.
Step 3: Run the agent
You have tools and a loop, so all that's missing is a model and its API key. Read keys from environment variables, never from source files.
# main.py
import os

from intelli.function.chatbot import Chatbot, ChatProvider
from order_agent import run_agent

bot = Chatbot(os.environ["OPENAI_API_KEY"], ChatProvider.OPENAI, options={"timeout": 60})
print(run_agent(bot, "gpt-5.5", "Where is my order A-1001 and when will it arrive?"))
Each tool call prints a line, so you can watch the agent work. The intended path is two tool steps: get_order_status returns the tracking number DHL-778120, get_shipment_eta uses it, and the third model call answers in text. The default timeout for a Chatbot call is 180 seconds. Set a lower one, as above, for anything customer-facing.
Run the same agent on OpenAI, Claude or a local model
That run used OpenAI, and you won't always want it to. Provider choice keeps changing for business reasons: price, rate limits, data residency, or a new model that is better at your task. The loop does not know which provider it talks to, so switching is a constructor change.
# switch.py
import os

from intelli.function.chatbot import Chatbot, ChatProvider
from intelli.utils.proxy_helper import ProxyHelper
from order_agent import run_agent

question = "Where is my order A-1001 and when will it arrive?"

# OpenAI: GPT-5 models go through the Responses API
openai_bot = Chatbot(os.environ["OPENAI_API_KEY"], ChatProvider.OPENAI)
print(run_agent(openai_bot, "gpt-5.5", question))

# Anthropic: same loop, tool specs converted by tools_for()
claude_bot = Chatbot(os.environ["ANTHROPIC_API_KEY"], ChatProvider.ANTHROPIC)
print(run_agent(claude_bot, "claude-sonnet-5", question))

# Local: Ollama's OpenAI-compatible server, no key and no bill
local = ProxyHelper()
local.set_openai_proxy_values({"base": "http://localhost:11434"})
local_bot = Chatbot("ollama", ChatProvider.OPENAI, options={"proxy_helper": local})
print(run_agent(local_bot, "qwen2.5:0.5b", question))
A few things happen behind those three calls:
gpt-5.5goes to the Responses API with the flat tool format. On that path Intelli merges all messages into one input string, so role structure is lost in long chats. GPT-5 models also acceptreasoning_effortandverbosityonChatModelInput.- For Claude,
tools_forswitches toinput_schema, and parallel calls arrive in the sametool_callslist. - The local bot is the OpenAI provider pointed at Ollama through a fresh
ProxyHelper, with a dummy key. Ollama's OpenAI-compatible endpoint accepts the same requests as OpenAI's API and supports tools, as its tool support announcement explains. Keep the model id from starting withgpt-5(that routes to the Responses API), and skip Intelli'svllmprovider here, because it does not forward tools.
The model switching page covers the other providers for plain chat.
What a 0.5B local model did in our tests
Switching is easy. Whether the new model can still do the job is another matter. We ran this exact loop against qwen2.5:0.5b, a model with half a billion parameters, on a laptop through Ollama. The results are a useful warning.
- The first lookup worked in all 35 runs: the model called
get_order_statuswithA-1001and replied sensibly. - It never made the second hop. Across all 35 runs and three different follow-up messages, it never called
get_shipment_eta, so it never had a real delivery date. - It sometimes invented one anyway: "by the next business day" with one follow-up message, and "within 3 days" in every run after we added the refund tool from the next section.
- One extra sentence in the system prompt, "Keep answers under three sentences", made it stop calling tools in 3 of 3 runs and ask for the order id it had just been given.
At temperature=0 the answers were identical run after run, so retrying does not help. The loop was fine; the model was too small to plan.
Use a local model for development, CI and demos where you pay nothing per token, and test the model you will ship before you trust any multi-step behavior. Larger local models are worth trying, but measure them on your own questions.
Add guardrails before you ship
That invented date is the lesson: the model only suggests, and your code decides what actually happens. The loop already has a step cap and a text-only last step. The remaining checks belong in run_tool, the one place where model output turns into real actions. Add this to order_agent.py and delete the first run_tool:
# order_agent.py (guardrails, replaces the first run_tool)
import logging
import re
import time

log = logging.getLogger("order_agent")
ORDER_ID = re.compile(r"^[A-Z]-\d{4}$")
NEEDS_APPROVAL = {"issue_refund"}


def issue_refund(order_id, amount):
    return {"order_id": order_id, "refunded": amount}  # your payments API call goes here


TOOLS["issue_refund"] = issue_refund
TOOL_SPECS.append({
    "name": "issue_refund",
    "description": "Refund an order. Needs human approval.",
    "parameters": {"type": "object",
                   "properties": {"order_id": {"type": "string"}, "amount": {"type": "number"}},
                   "required": ["order_id", "amount"]},
})


def run_tool(name, raw_args, approve=None):
    fn = TOOLS.get(name)
    if fn is None:
        return {"error": f"unknown tool {name}"}
    try:
        args = json.loads(raw_args or "{}")
    except json.JSONDecodeError:
        return {"error": "arguments were not valid JSON"}
    if not isinstance(args, dict):
        return {"error": "arguments must be a JSON object"}
    if "order_id" in args and not ORDER_ID.match(str(args["order_id"]).strip().upper()):
        return {"error": "order ids look like A-1001"}
    if name in NEEDS_APPROVAL and not (approve and approve(name, args)):
        return {"error": "refunds need a human. Tell the customer a teammate will follow up."}

    started = time.perf_counter()
    try:
        result = fn(**args)
    except TypeError as err:
        return {"error": f"bad arguments for {name}: {err}"}
    log.info("tool=%s args=%s ms=%.0f", name, args, (time.perf_counter() - started) * 1000)
    return result
What this buys you:
- Argument validation. The model chose those arguments. Check them like user input before they reach a database.
- An approval gate for side effects. Read-only tools run freely. Anything that moves money, sends email or changes records goes in
NEEDS_APPROVAL. Becauseapprovedefaults toNoneandrun_agentnever passes one, every refund is refused until you wire in a real approval step, such as a button in your support console. - A log line per tool run. Tool name, arguments and latency are what you need when a customer says the bot gave them the wrong date. Call
logging.basicConfig(level=logging.INFO)once at startup to see them. - Bounded cost.
max_tokens=1000bounds each reply andmax_stepsbounds the number of calls. Together they cap the worst-case cost of any single question, andoptions={"timeout": 60}caps how long each call can wait.
One gap to plan for: the Chatbot returns message content only, not the provider's token usage. For cost per conversation, count model calls per question in your own logs and reconcile them with the provider's usage dashboard.
When one agent is not enough
You now have one guarded loop that does one job well. Real processes chain jobs: look up the order, then write the customer email in your brand voice, maybe on a different model. Intelli flows cover that: a flow wires tasks together so one task's output feeds the next, and you can wrap the loop you already wrote as one step.
# flow.py
import asyncio
import os

from intelli.flow import Agent, CustomAgent, Flow, Task, TextTaskInput
from intelli.function.chatbot import Chatbot, ChatProvider
from order_agent import run_agent


class OrderLookup(CustomAgent):
    """Runs the tool calling loop as one step of a flow."""

    def __init__(self, bot, model):
        super().__init__(agent_type="text")
        self.bot, self.model = bot, model

    def execute(self, agent_input, new_params=None):
        return run_agent(self.bot, self.model, agent_input.desc)


lookup = OrderLookup(Chatbot(os.environ["OPENAI_API_KEY"], ChatProvider.OPENAI), "gpt-5.5")
writer = Agent("text", "anthropic", "You write short, friendly customer emails.",
               {"key": os.environ["ANTHROPIC_API_KEY"], "model": "claude-sonnet-5"})

flow = Flow(
    tasks={
        "lookup": Task(TextTaskInput("Where is my order A-1001 and when will it arrive?"), lookup),
        "email": Task(TextTaskInput("Write a three line email to the customer with this update."), writer),
    },
    map_paths={"lookup": ["email"]},
)
result = asyncio.run(flow.start())
print(result["email"]["output"])
CustomAgent turns any Python code into a flow step, so your tested loop runs unchanged inside it. The flow passes the lookup answer into the writer's prompt, and result holds one entry per task with its output. Here the lookup runs on GPT-5.5 and the email on Claude, a split you might pick when one model is cheaper for tool use and another writes better copy. The Agent docs list the built-in agent types.
Where you go next depends on your tools. If they already live behind an MCP server (the Model Context Protocol is an open standard for connecting AI apps to tools and data), ToolDynamicConnector can send the flow to an MCP task when the model calls a tool, and a small pre_process step maps the call's name and arguments onto that task. See dynamic tool routing and the MCP client. If you need branching, loops and parallel steps, read Agentic Workflows in Python Without LangGraph. LangGraph, a framework for building agents as graphs, comes up next.
Write your own loop or adopt a framework
You've seen what a hand-written agent needs and where it gets thin. That leaves the real decision: keep your own loop, or adopt a framework.
The raw provider SDK is enough if you are committed to one provider and have a couple of tools. That's each vendor's official client library, and you can write this loop against the OpenAI or Anthropic SDK in an afternoon. The hard part of shipping an agent is the tools and the test questions, not the loop.
Intelli earns its place when you want to keep provider choice open: one reply shape across OpenAI, Anthropic and OpenAI-compatible servers, one constructor to switch, and a path from a single loop to flows and MCP without a rewrite. Your team writes plain Python functions, not a graph DSL (a special syntax for wiring agents into graphs).
Know the limits. Tool calls are parsed for OpenAI (chat completions and Responses), Anthropic and OpenAI-compatible endpoints. Intelli forwards tools to Gemini and Mistral but does not turn their tool calls into tool_response today, so this loop will not work on them yet. There is no native tool result message, replies carry no token usage, and the community is far smaller: openai-agents alone had about 12 million PyPI downloads in the last 30 days, according to pypistats on September 30, 2026.
Pick a bigger framework when its built-ins match your needs. The OpenAI Agents SDK ships handoffs between agents, guardrails, sessions and tracing, and supports other providers through adapters such as LiteLLM. The Claude Agent SDK gives you the agent loop, built-in file, shell and web tools, permissions and hooks that power Claude Code, in Python and TypeScript. LangGraph is a low-level orchestration runtime for long-running, stateful agents, with persistence and human-in-the-loop support. If you need a workflow that resumes after a crash, LangGraph is built for that and a hand-written loop is not.
FAQ
Do I need LangChain or another framework to build an AI agent in Python?
No. An agent is a loop around model calls, and the version here fits in one file. Frameworks pay off when you need their built-ins, such as tracing, handoffs or durable state. Adopt one when you can name the feature you are missing.
What is the best model for a Python AI agent?
Start with a strong hosted model so you know the loop and tools work, then try cheaper models on the same test questions. A model can chat well and still fail at tool use, as the 0.5B test above shows, so measure tool calls directly. Because switching is a constructor change, comparing models is cheap.
Can I create an AI agent locally in Python?
Yes. Point the OpenAI provider at Ollama with ProxyHelper, as shown above, and the agent runs with no API key and no per-token cost. In our tests a 0.5B model called one tool reliably but never chained two, so use a larger local model for multi-step tasks and test it on your own data.
How many steps should an AI agent loop allow?
Set the cap a little above the longest path you expect. The order agent needs two tool steps plus an answer, so max_steps=5 leaves room for one retry. Log how often requests hit the cap, because a rising number usually means a tool description or error message is confusing the model.
How much does it cost to run an AI agent?
Each step is one model call that resends the growing conversation, so a two-tool answer costs about three calls. Multiply by your ticket volume and your provider's token prices for a monthly estimate. Step caps, short tool results and a local model for development keep it predictable.
Start building
To try it on your own inbox, install the package and copy order_agent.py from this article:
pip install intelli
Then swap the fake ORDERS dict for your real order API, keep max_steps and the approval gate, and run it against a local model first. The tool calling guide covers tool_choice and each provider's tool format, and the installation page lists the optional extras, such as pip install "intelli[mcp]" for MCP support.
To let Claude Code or Codex build tools like this for you, see Give IntelliNode to Claude Code or Codex to Build AI Agents.